Short answer: llms.txt is a Markdown file that gives AI agents a short map of your site. It is cheap to add, and Google says it neither harms nor helps in Google Search, which ignores the file. OpenAI, Anthropic and Perplexity do not mention it in their crawler documentation. One vendor's log study found their crawlers barely fetch it. Add one if you run developer docs or want agents to find key pages. Do not expect rankings or citations from it.
What is llms.txt, and who proposed it?
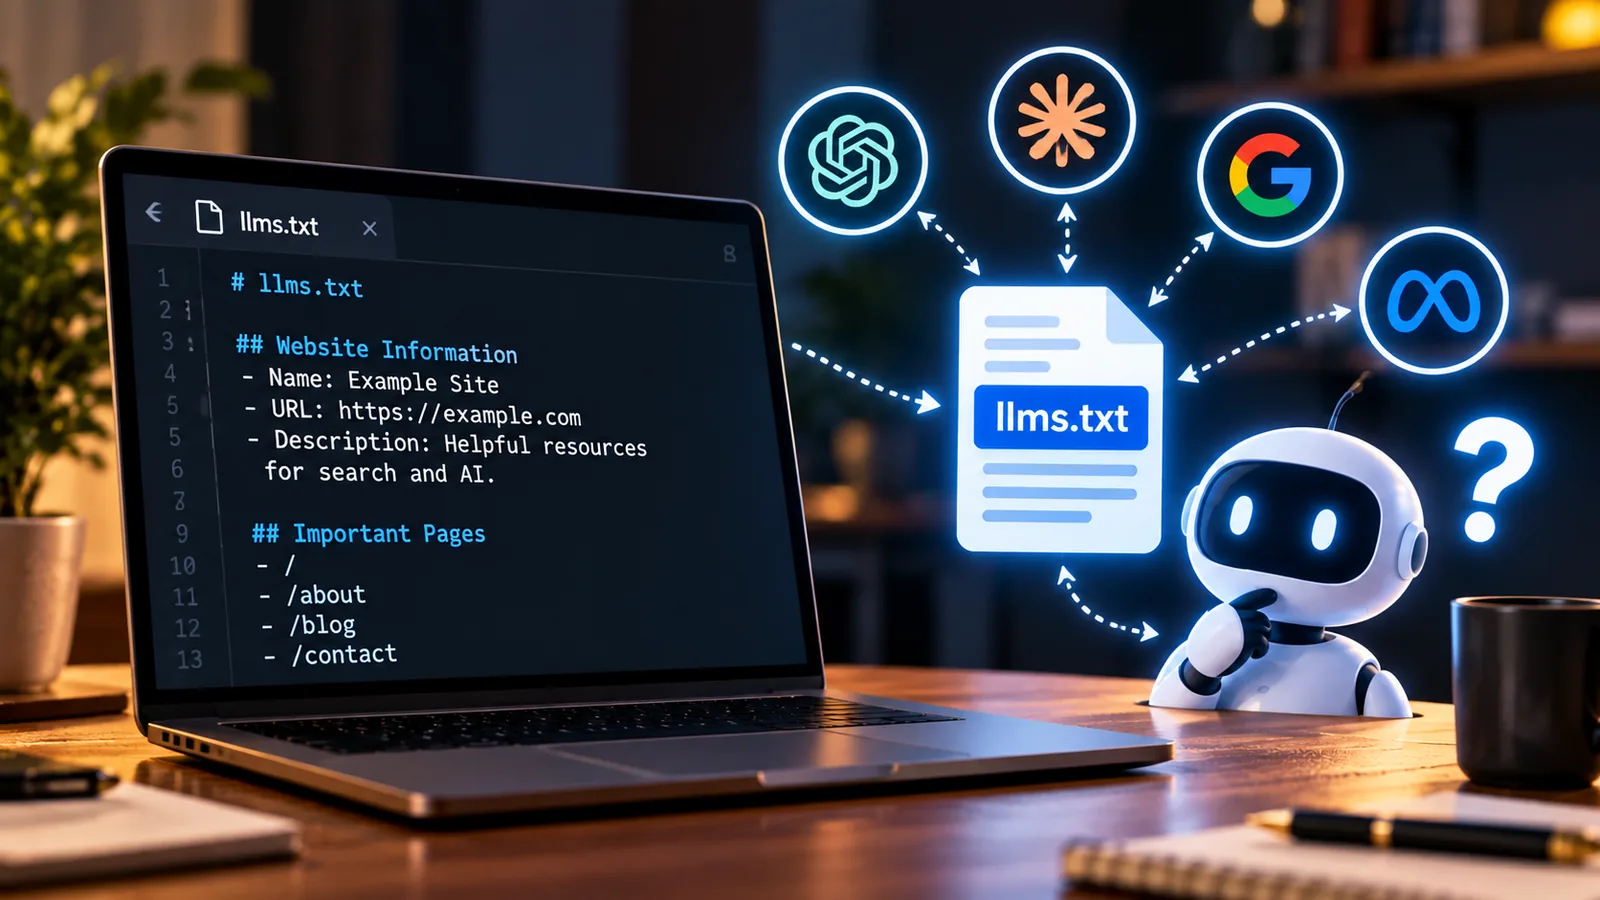
llms.txt is a plain text file written in Markdown. It sits at the root of a site, at /llms.txt, much like robots.txt does. Its job is to give a language model a short, curated guide to the site, with links to the pages that matter most.
Jeremy Howard published the llms.txt proposal on 3 September 2024. The page describes it as "A proposal to standardise on using an /llms.txt file to provide information to help agents use a website." The core idea is stated plainly:
"We propose adding a /llms.txt markdown file to websites to provide LLM-friendly content. The file can be placed at the site root, or at any path within it, covering the pages under that path. This file offers brief background information, guidance, and links to detailed markdown files."
The proposal also suggests that sites offer clean Markdown copies of key pages, at the same URL with .md added. The proposal notes that an HTML page wraps its information in navigation, ads and JavaScript, and that converting it back into clean text "is difficult and imprecise." A Markdown copy skips that step.
The proposal moved to version 2 in August 2026. It adds standard link tags so an agent can find a page's Markdown copy and the llms.txt that covers it.
Note who the file is for. The proposal says it is "used most heavily for software documentation." That is a narrower audience than most SEO posts suggest.
What does an llms.txt file look like?
The format is simple. The spec lists the sections in a fixed order:
- An H1 with the name of the site or project. This is the only required part.
- A blockquote with a short summary.
- Optional paragraphs or lists with more detail. No headings here.
- Optional H2 sections, each holding a "file list" of links.
Each item in a file list is a Markdown link, then an optional colon and a note. The spec adds that a section named "Optional" is used, by convention, for links an agent can skip when it needs a shorter context.
Here is a short example for a made-up business:
# Example Plumbing Co

> Licensed plumbers serving Springfield since 2010. We fix leaks,
> install water heaters and offer 24-hour emergency callouts.

We serve residential and small commercial customers within 30 miles
of Springfield. Prices on the pricing page are starting prices.

## Services
- [Emergency plumbing](https://example.com/emergency.md): 24-hour callouts and response areas
- [Water heaters](https://example.com/water-heaters.md): Repair and replacement, brands we install

## Company
- [Pricing](https://example.com/pricing.md): Starting prices and callout fees
- [Contact](https://example.com/contact.md): Phone, hours and booking form

## Optional
- [Blog](https://example.com/blog.md): Maintenance tips and seasonal advice
The links point to .md files. If you have no Markdown copies, link to the normal HTML pages instead.
Does Google use llms.txt?
No, not for Search. Google says so in writing. Its guide to optimizing for generative AI features, last updated on 10 July 2026, lists llms.txt under "what you don't need to do":
"You don't need to create new machine readable files, AI text files, markup, or Markdown to appear in Google Search (including its generative AI capabilities), as Google Search itself doesn't use them."
The same section adds a line that settles the ranking question:
"It's completely fine if you decide to create and maintain LLMS.txt files (or other similar files) for other services or systems that use these files. Doing so will neither harm nor help your site's visibility or rankings in Google Search, as Google Search ignores them."
Google also notes that it "may discover, crawl, and index many kinds of files" beyond HTML. A Googlebot fetch of your llms.txt is normal crawling, not special treatment.
John Mueller of Google has said much the same on Bluesky. In June 2025, a site owner said they had turned on llms.txt to be found by AI answer engines. Mueller replied: "FWIW no AI system currently uses llms.txt."
In January 2026, someone spotted an llms.txt on a Google developer site and asked if that was an endorsement. Mueller answered: "I'm tempted to say something snarky since this has come up so often, but to be direct, no."
So why does Lighthouse check for it?
Chrome's Lighthouse is the only Google tool with a documented llms.txt check. It has an llms.txt audit in its Agentic Browsing category. It says that without it, "agents may spend more time crawling the site to understand its high-level structure and primary content."
Read the details before you treat this as a signal. The audit only flags a server error. A missing file "is marked as Not Applicable (N/A), as providing the file is optional at the moment." The scoring page says the whole category is "experimental and based on proposed standards" and has no weighted 0 to 100 score. Lighthouse is a Chrome developer tool, not Google Search.
Do ChatGPT, Claude and Perplexity read llms.txt?
None of them say so in their crawler documentation. I read each company's page on its bots. All three point site owners to robots.txt. None of the three pages mentions llms.txt in its main body text.
- OpenAI's crawler overview says: "OpenAI uses OAI-SearchBot and GPTBot robots.txt tags to enable webmasters to manage how their sites and content work with AI."
- Perplexity's bots page says: "Webmasters can use the following robots.txt tags to manage how their sites and content interact with Perplexity."
- Anthropic's crawler help article says its bots honor "industry standard directives in robots.txt."
I also looked for any primary statement that their crawlers or answer engines read llms.txt from other sites. I found none. A company could read the file without saying so, but no one has documented it.
What do server logs show?
One log study gives a rough picture. EZY Research watched 83 sites with llms.txt live for 12 weeks, from 27 April to 19 July 2026. It counted how often each crawler fetched robots.txt versus llms.txt.
| Crawler | robots.txt fetches | llms.txt fetches |
|---|---|---|
| OpenAI | 3,990 | 7 |
| Anthropic | 3,120 | 9 |
| PerplexityBot | 775 | 0 |
| Googlebot | 5,125 | 67 |
| Meta-ExternalAgent | 172 | 193 |
Keep three limits in mind. EZY sells llms.txt generation, and says so. It also states that its "Panel skews toward small-business sites whose owners sought an AI-visibility tool." And it counted file fetches, not citations or rankings. So the numbers tell you who opens the file, not whether opening it changes anything.
Even so, the pattern matches what the companies publish. The main AI search crawlers fetched robots.txt hundreds to thousands of times and llms.txt a handful of times. Meta's crawler was the exception.
If nobody reads it, why do OpenAI, Anthropic and Google publish one?
They do publish them. The proposal itself notes that "The AI labs themselves publish llms.txt files for their own developer docs: OpenAI, Anthropic, and Gemini." I fetched several on 2 October 2026 to check.
| File | Status | What it covers |
|---|---|---|
| docs.anthropic.com/llms.txt | Live (redirects to platform.claude.com) | Anthropic developer documentation |
| developers.openai.com/llms.txt | Live | OpenAI developer documentation |
| ai.google.dev/gemini-api/docs/llms.txt | Live | Gemini API documentation |
| docs.perplexity.ai/llms.txt | Live | Perplexity API documentation |
| docs.stripe.com/llms.txt | Live | Stripe documentation |
| www.anthropic.com/llms.txt | 404 | None on the main company site |
| www.google.com/llms.txt | 404 | None on the main search site |
Look at where the files live. Almost all sit on developer documentation subdomains. That fits the proposal's own use case, where coding agents follow the file to find API references and tutorials.
What this proves is narrow. These companies think llms.txt helps agents read their own docs. It does not prove that their answer engines read your llms.txt when choosing what to cite. Mueller's January 2026 reply makes the same point for Google.
What is llms.txt not?
Much of the confusion comes from treating llms.txt as something it was never meant to be.
| File | What it does | Who documents using it |
|---|---|---|
| robots.txt | Tells crawlers which paths they may fetch | Google, OpenAI, Anthropic and Perplexity crawler docs |
| sitemap.xml | Lists the indexable pages on a site | Search engines |
| llms.txt | Gives agents a curated summary and key links | The proposal and some docs and agent tools; no major AI search crawler |
It is not robots.txt. The proposal puts it directly: "robots.txt and llms.txt have different purposes." robots.txt says what bots may access. llms.txt is "used on demand, when an agent needs information about a topic while assisting a user." Putting "Disallow" lines in llms.txt will not block anything. If you want to block or allow AI crawlers, edit robots.txt.
It is not a ranking signal. Google says the file will "neither harm nor help" your visibility in Search. No other AI search company has documented a ranking or citation effect.
How do you write an llms.txt in 10 minutes?
If you decide to add one, keep it small. The proposal says the file should stay "small enough to fit in context."
- Write the H1. Use your site or brand name, nothing else.
- Write one blockquote. Two sentences on who you are and what you offer. Use plain facts, not slogans.
- Add a short note if needed. Mention anything an agent could get wrong, such as service area or what you do not offer.
- Pick 5 to 15 key pages. Group them under H2 headings such as Services, Docs or Company.
- Add a one-line note to each link. Say what the page answers, not how great it is.
- Put secondary links under "Optional". Blog archives and older material go here.
- Upload it to /llms.txt. Serve it as plain text and check that it returns a 200 status.
The proposal offers one useful test: "Test your file by asking an agent questions about your content, giving it only your llms.txt as a starting point."
On WordPress or Wix, you may not need to write it by hand. The proposal lists Yoast SEO, AIOSEO and Wix among tools that generate one. Check the output before you rely on it.
Keep it in sync with your site, because a stale file sends agents to dead pages. And do not stuff it with keywords.
When is llms.txt worth the time?
Worth doing: you publish software documentation, an API or a developer tool. This is where the file is used most. The proposal says coding agents follow these files to find API references and tutorials.
Fine to do, low priority: you run a business or content site and it takes 10 minutes or one plugin setting. Just do not count it as AI search work.
Not worth paying for: someone sells you llms.txt as a way to rank in AI Overviews or get cited by ChatGPT. Google says Search ignores it. The other companies have documented nothing. That claim runs ahead of the evidence.
If you are unsure whether your site has one, my free AI visibility checker reports whether an llms.txt is present. It does not score the file as a ranking factor, because no search engine has said it is one.
What should you work on instead?
If your goal is to show up in AI answers, start with the things AI companies do document. Make sure robots.txt does not block OAI-SearchBot or PerplexityBot. Both companies recommend allowing these bots if you want to appear in their results. Then write pages that answer real questions clearly.
For its own Search, Google's guide makes a similar point in its takeaways: "For Google Search, you can ignore tactics like "chunking" content, creating unnecessary AI text files (like llms.txt), or pursuing inauthentic mentions." Its advice is to keep "prioritizing foundational SEO best practices" and to create content that is "helpful, reliable, and people-first".
If the terms GEO and AEO are new to you, my guide to SEO vs GEO vs AEO explains how they differ. If you want help with visibility in AI answers, see my GEO service.
Frequently asked questions
What is llms.txt?
llms.txt is a Markdown file placed at /llms.txt on a website. It gives AI agents a short summary of the site and a curated list of links to key pages. Jeremy Howard proposed it in September 2024, and a second version followed in August 2026. It is a community proposal, not an official web standard.
Does llms.txt help SEO or Google rankings?
No. Google's guide to generative AI features says Search does not use llms.txt. It adds that creating one "will neither harm nor help" your visibility or rankings in Google Search. The guide applies this to Google's generative AI features as well. Treat the file as a helper for agents, not an SEO task.
Does ChatGPT or Perplexity read llms.txt?
Neither company says so. OpenAI's and Perplexity's crawler pages explain control through robots.txt and do not mention llms.txt. A vendor log study of 83 sites over 12 weeks counted 7 llms.txt fetches by OpenAI and none by PerplexityBot. That study measured fetches only, not citations, so it cannot show any effect on answers.
Is llms.txt the same as robots.txt?
No. robots.txt tells crawlers which parts of a site they may access. OpenAI, Anthropic and Perplexity all document robots.txt controls for their crawlers. llms.txt is a guide that points agents to useful pages when they need information. It blocks nothing. If you want to allow or block AI bots, you need to edit robots.txt, not llms.txt.
Should a small business add an llms.txt file?
It can, if it takes minutes or a plugin setting. Google says it neither harms nor helps in Google Search, and it may help agents that read it. But no major AI search engine has documented using it, so it should not take time away from your pages and your robots.txt settings. Do not pay for llms.txt sold as a ranking or citation fix.
Why do AI companies publish llms.txt if they do not read it?
Anthropic, OpenAI, Google and Perplexity publish llms.txt files on their developer documentation sites. Those files help developers and coding agents find the right docs pages. Publishing a file for your own docs is different from reading other sites' files for search. Google's John Mueller said a file on a Google site is not an endorsement.